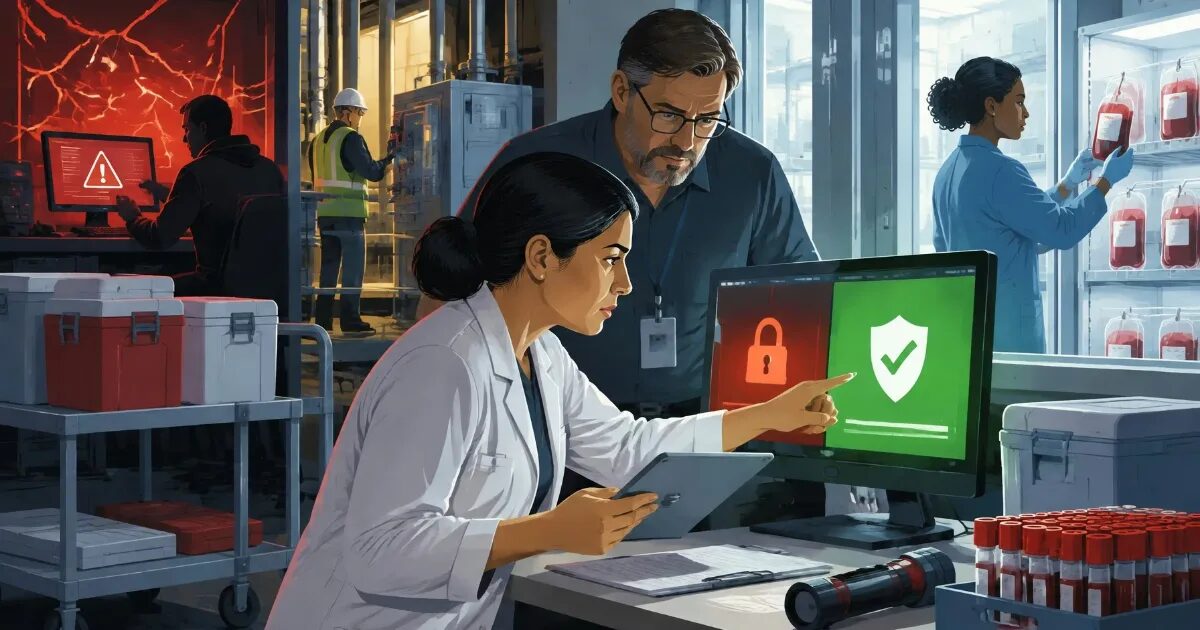
Bringing a refrigeration controller back online doesn’t tell a supermarket manager if the food inside is still safe to sell.Somebody still has to determine how warm the unit got and how long it stayed that way.When temperature logs are missing or untrustworthy, restoring the software leaves the hardest operational decision unresolved.ContentsKey Takeaways for Operational Integrity After a BreachThe Blood-Storage Incident Shows Why Detection Needs a Response PlanManual Operation Has to Be Practised Before It Is NeededA Compromised AI Account Can Run Up a Bill Before Anyone NoticesGive Operational AI Agents Less Room to Make Expensive MistakesAsk Suppliers to Demonstrate How Access Can Be WithdrawnRecovery Needs a Measurement Beyond “Systems Restored”Make the Next Exercise a Supplier OutageFrequently Asked QuestionsWhy is getting a controller back online insufficient to confirm recovery?How can organizations verify whether temperature or telemetry data is trustworthy after a breach?What steps should teams take to ensure vendor remote access can be safely revoked during an incident?Cyberattack recovery trust rests on evidence, since a green status light proves little about product safety.
Rebuild trusted access, check backup integrity, and compare controller readings with independent measurements before normal work resumes.NIST SP 800-53 CP-10 describes the goal as recovery to a trusted operational state.Operations staff should then sign off on physical stock, records, and unresolved gaps.Rebuild trusted access, check backup integrity, and compare controller readings with independent measurements before normal work resumes.Refrigeration monitoring only protects inventory when staff can act on the alarm.Manual fallback has to be rehearsed and measured before an outage.Recent reports of attacks on European refrigeration systems put this data integrity problem into sharp relief.
In a scenario like this, an altered setting could spoil inventory fast.Worse, uncertainty about what happened can keep usable goods off the shelves while staff investigate the telemetry.On November 9, France attributed the October 12 supermarket refrigeration attack to Iran, according to the Associated Press.The attribution report put the impact at roughly 700 French supermarkets.
That attribution covers one specific incident; it doesn’t point to a single culprit behind every recent disruption across European retail.Sources: evidence In a separate case, Ahold Delhaize’s November 4 financial update estimated that its October cybersecurity incident would cut fourth-quarter sales by €200 million to €250 million.The retailer also projected a €75 million to €100 million hit to operating income.
Those figures are the company’s projections, not a final loss calculation.For organizations reviewing their own risk exposure, the immediate question is simple: how much operational state can you verify without trusting the compromised system?Key Takeaways for Operational Integrity After a BreachRecovery teams should treat restored connectivity as one milestone, then verify access, telemetry, and the work itself.CSO Online notes that attacks can leave teams unsure which systems, credentials, or data copies they can rely on.Independent checks and operational sign-off close that gap.Rebuild trust in access.
Review privileged accounts and management paths before relying on restored applications.A recovered server still poses a risk if the old administrative access remains compromised.Check telemetry out of band.Use readings that don’t depend on the compromised controller, then compare them with product condition, alarm history, and physical inspection results.Practise manual procedures.
Measure the work your team can complete safely without primary software, and record its actual capacity and unresolved gaps.The Blood-Storage Incident Shows Why Detection Needs a Response PlanRefrigeration monitoring only protects inventory when staff can act on the alarm.In the reported scenario, a November 2 cyberattack hit equipment at three French Blood Establishment sites and changed temperature and defrosting thresholds.According to the EFS statement reported by AP, staff stepped in immediately, and no blood products or samples spoiled.
The operational lesson matters just as much as the attempted sabotage: staff need a reliable warning and enough time to act while inventory remains safe.More Read What To Know About The Impact of Data Quality and Quantity In AI New Startup Uses AI to Help Forex Traders Make Better Insights Data-Driven Tips to Optimize the Speed of Macs 7 Mind-Blowing Facts You Didn’t Know About AI Manual Testing Tools Can Outperform AI with Quality Assurance If you run a similar installation, start your review with a practical failure scenario: assume your supplier’s remote-management service is down or compromised.Ask your facilities team to show where they would pull trustworthy temperature readings, who gets the overnight alert, and who holds the authority to move stock.Have an equipment specialist verify whether monitoring and control systems share credentials or underlying dependencies.A secondary dashboard offers very little protection if the same hijacked account can alter operating setpoints and silence the alarms at the same time.Subject every network disconnection or local-control procedure to a proper engineering review.
Yanking an Ethernet cable without knowing how the controller fails over can trigger a brand-new operational crisis.Manual Operation Has to Be Practised Before It Is NeededManual fallback has to be rehearsed and measured before an outage.In its company account of the March 2019 cyberattack, Hydro reported that several business areas maintained production close to normal by falling back on labor-intensive workarounds and manual procedures.Its Extruded Solutions division, however, faced much deeper disruption.
That contrast gives recovery planners a concrete test to run.Pick one essential operation and map out what your floor staff can safely run without their primary software.Verify whether printed instructions, emergency contacts, and active order specs stay accessible when the network goes dark.Document the hard limits of those manual workflows.
A fallback process that pushes through a few urgent orders is still useful even if it can’t match normal daily throughput.Leadership needs to know that exact ceiling before promising customers a recovery timeline.Compromised AI accounts add a direct financial risk: excessive permissions can turn stolen access into a compute bill.A Compromised AI Account Can Run Up a Bill Before Anyone NoticesSome threat actors chase a direct financial payout.They hijack a victim’s cloud environment to spin up AI workloads, leaving the legitimate account owner stuck with the compute bill.In its investigation of LLMjacking, Mandiant documented individual breaches where fraudulent resource charges topped $100,000 in a single day.
At some targeted organizations, cumulative charges reached $1 million before access was revoked.Those figures are observations from specific incidents, not a baseline cost for every compromised account.Your actual financial exposure hinges on what a stolen credential allows an attacker to do.
A service account built for a narrow task needs tight scrutiny if it can also enable new cloud APIs or provision high-cost compute instances.Direct your cloud administrators to audit machine identities right alongside human user accounts.Map out exactly which identities can invoke foundation models, spin up infrastructure, or modify IAM permissions.Strip away access that lacks an active business justification, and assign a specific owner to review every exception.Tie your billing alerts directly to an operational response.
Decide right now who investigates an after-hours cost spike and who holds the authority to kill the runaway workload.Check whether your cloud provider supports hard quotas or automated spending caps for the specific AI service in question.An email alert that flags runaway spending won’t stop the meter from running.Give Operational AI Agents Less Room to Make Expensive MistakesLimit operational AI agents by requiring human approval for high-impact actions and enforcing hard-coded safety limits before granting permissions.
When an agent acts on an equipment alert, whether opening a maintenance ticket, tweaking a controller setpoint, or ordering replacement inventory, each step carries a distinct risk profile.At first, have the agent inspect telemetry and draft a proposed action.Keep high-impact changes behind a human approval gate until your engineers have thoroughly tested the boundary conditions for safe automation.Physical machinery must retain hard-coded engineering safety limits no matter who – or what – requests a parameter change.
Log the underlying data behind every automated decision.If an agent orders replacement stock because it thinks a commercial freezer failed, an auditor should be able to trace that purchase order straight back to the raw sensor readings.A stale or spoofed sensor value shouldn’t pass through middleware and come out the other side looking like a verified purchasing directive.Test your kill switches before going live.
Disable the agent’s identity during a controlled drill, then observe what halts, what stays stuck in a message queue, and how human operators step in to take over.Bring third-party vendors into the drill whenever their systems touch the workflow.Apply the exact same governance to human maintenance accounts: every credential needs a named owner, a scoped purpose, and a tested revocation path.Handing the work over to software makes those basic hygiene rules even more urgent.Ask Suppliers to Demonstrate How Access Can Be WithdrawnYour maintenance contracts should spell out how vendors connect to your equipment and what happens the moment that connection turns risky.
Demand a live demonstration on a test system.A paper promise that remote access can be revoked leaves too many operational questions hanging.Verify whether vendor technicians log in with individual named accounts, whether their permissions are locked down to the specific machines they service, and whether access automatically expires when the ticket closes.
Identify any third-party subcontractors in the chain.Your internal team needs to know exactly who to call if an unfamiliar remote session pops up at 2 a.m.Next, walk through the cutoff sequence live.Have the supplier open an authorized session, revoke their own access, and prove that the connection drops immediately.
Check whether the technician can sneak back in through a secondary jump host or backup support tool.Document any technical dependency that stops your internal staff from severing the link without the vendor’s cooperation.Build forensic evidence requirements into the contract too.Agree upfront on which access logs and configuration histories the vendor will hand over after an incident, who can request them, and how long they stay in retention.
An operations team trying to reconstruct an unauthorized temperature swing needs raw audit trails, not a summary ticket stating that routine maintenance took place.Recovery Needs a Measurement Beyond “Systems Restored”Track two separate timestamps during incident recovery: when a system comes back online, and when the business verifies that its data and physical state are trustworthy.Those two milestones can sit hours or even days apart.For a cold-storage operator, true verification means auditing temperature logs and inspecting physical stock under established quality-control protocols.
For a distribution warehouse, it means reconciling physical inventory movements made on paper during the outage.Put the people who run those daily operations in charge of defining the verification checklists before a breach happens.Use your next recovery drill to measure that verification gap:Treat these checkpoints as practical drill metrics, not a universal compliance standard.Their real value lies in surfacing specific blind spots that your engineering team can actually fix.Make the Next Exercise a Supplier OutageFor your next planning cycle, pick one critical vendor whose sudden loss would halt a core business operation.
Put the facilities manager, the IT system owner, and the supplier’s technical lead into the same room for a joint exercise.For the drill, assume that remote vendor support could be completely unreachable for a full shift.Map out which workflows keep moving, which operational calls require local floor expertise, and which historical logs your staff can’t pull on their own.Never test risky equipment state changes on live production gear; stick to a tabletop walkthrough or a sandboxed test rig.Assign a single owner and a hard deadline to every unresolved dependency you uncover.
Once the fixes are in place, run the drill again, and require a live handover to an operator who didn’t write the original playbook.Post-attack confidence rests on hard evidence.Your team needs to know which sensor readings they validated, which credentials they killed, and which manual fallbacks they proved out.Defending a public recovery announcement gets much easier when those audit records are already sitting in your hands.Frequently Asked QuestionsWhy is getting a controller back online insufficient to confirm recovery?Getting a controller back online is insufficient to confirm recovery because restored connectivity proves little about product safety or whether the food inside is safe to sell.
Somebody still has to determine how warm the unit got and how long it stayed that way.Restoring software leaves the operational decision unresolved when logs are missing.Recovery requires rebuilding trusted access, checking backup integrity, and comparing controller readings with independent measurements before normal work resumes.How can organizations verify whether temperature or telemetry data is trustworthy after a breach?Organizations can verify whether temperature or telemetry data is trustworthy after a breach by checking telemetry out of band and comparing controller readings with independent measurements.
Teams should pull readings that do not depend on the compromised controller, then compare them against product condition, alarm history, and physical inspection results.Operations staff then sign off on physical stock, records, and unresolved gaps before normal work resumes.What steps should teams take to ensure vendor remote access can be safely revoked during an incident?Teams should take clear steps to ensure vendor remote access can be safely revoked during an incident by demanding a live demonstration on a test system.Have the supplier open an authorized session, revoke access, and prove the connection drops immediately.
Check whether technicians use individual named accounts, ensure permissions expire when tickets close, test secondary jump hosts, and document any technical dependency that prevents internal staff from severing links independently.
Read More